 Vipin PG
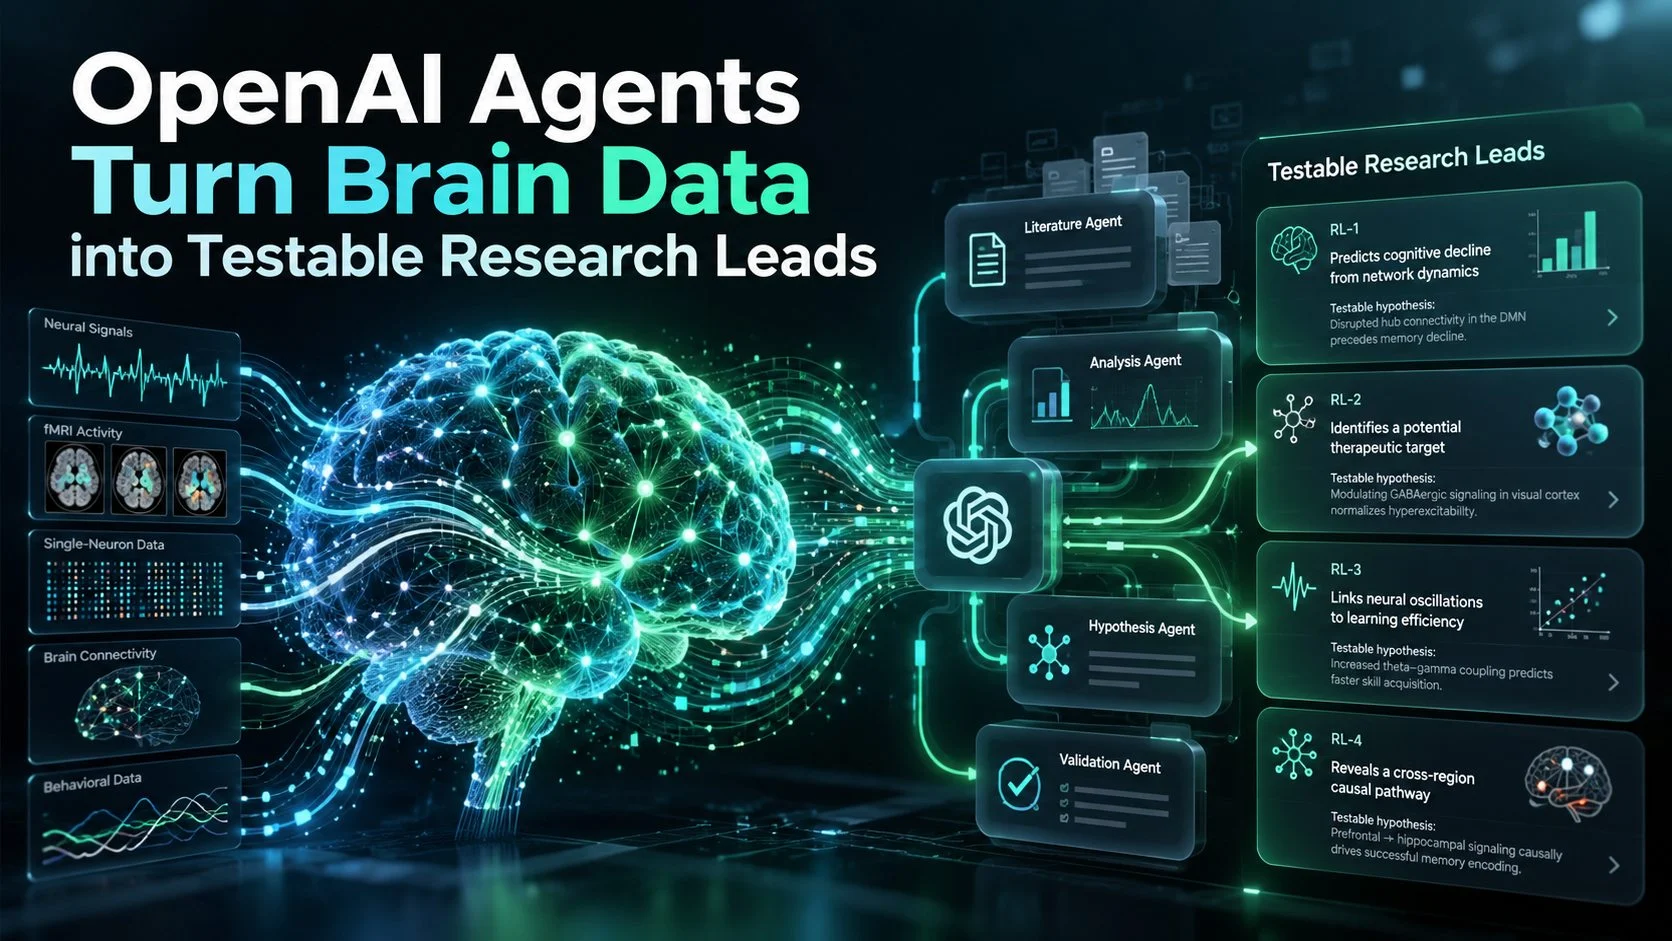
OpenAI says 1,946 AI agents analyzed an existing mouse-brain gene-disruption atlas in 32 minutes, producing research leads that would be difficult to surface one perturbation at a time. The agents did not run the experiment. They interpreted data from millions of cells, connected expression changes to published literature, and assembled reports into a searchable map.
The work tests whether biological reasoning can be split across many focused agents and brought together without losing the evidence trail. It makes no claim of a new treatment or a confirmed disease mechanism. For computational biologists, the question is whether this can help prioritize experiments, and how much the reported benchmarks establish.
The authors call the approach distributed biological reasoning. They applied it to a whole-brain CRISPR Perturb-seq atlas. Perturb-seq combines targeted gene disruption with single-cell gene-expression measurement, allowing researchers to see how cells respond in context. The team’s OpenAI project account describes the system as a way to turn unexpected observations into questions researchers can test.
Interpretation is the bottleneck
Large perturbation screens can reveal thousands of cellular responses, but those measurements do not interpret themselves. Differential expression, the change in gene activity between perturbed and control cells, can identify patterns. Connecting those patterns to cell type, disease context, biological mechanism, and prior research takes more work.
The preprint frames that gap as a limit on what researchers can extract from experiments that measure many variables at once. A screen can produce tens of thousands of perturbation-by-cell-type observations, and interpreting them requires moving between statistical results, biological knowledge, and literature written across different fields. Conventional analysis may identify pathways or gene lists while leaving important cell-specific relationships unexplored.
The agents worked on top of an existing experimental dataset. They were asked to expand the interpretive layer researchers can apply to the data, and the underlying observations remain those of the mouse experiment. The workflow can generate candidate explanations, but it does not add measurements.
Distributed biological reasoning splits the analysis
The system divided the screen into smaller tasks, assigning an independent agent to each perturbation. The authors report that 1,946 agents ran in parallel. Each received cell-type-resolved differential-expression profiles, experimental context, a shared prompt and coding environment, analytical tools, and access to literature.
Agents produced structured reports rather than a single free-form answer. Each report included findings, quantitative evidence, an interpretation, references, caveats, and possible follow-up experiments. The model was GPT-Rosalind-5.5, and the paper gives its knowledge cutoff as December 2025, before the source atlas manuscript appeared in March 2026. The team says it withheld that manuscript and its conclusions from the agents during analysis.
A second stage combined the reports. The authors organized them in a searchable database and knowledge graph, connecting perturbations to genes, cell types, pathways, reported findings, and supporting evidence. Readers can move from an individual expression pattern to a broader comparison while retaining the context behind each entry.
The mouse-brain atlas the system inherited
The underlying study used an enhanced in-vivo Perturb-seq method to examine gene disruptions across the mouse brain. Its preprint reports targeting 1,947 disease-associated genes and profiling more than 7.7 million cells across major brain regions and neuronal populations. The study used pooled CRISPR guide RNAs and single-nucleus RNA sequencing to measure transcriptome-wide responses.
Those measurements show which genes’ expression changed after a perturbation and how the response differed across cell types. On their own, they do not prove every downstream mechanism proposed to explain a pattern. The atlas study reports cell-type-specific responses and cases in which related genes produce opposing transcriptional programs, observations that can motivate follow-up experiments.
The numbers 1,947 and 1,946 refer to different things. The atlas preprint says it targeted 1,947 genes, while the distributed-agent paper says it ran 1,946 agents for the analysis. The public PerturbAI atlas dataset exposes cell-level expression and annotations, including brain-region and cell-type fields. It is a company-maintained resource and has not been independently validated against the later interpretations.
What the reasoning atlas contains
The public output is meant to be more than a catalog of AI conclusions. The paper describes reports and a graph linking findings to perturbations, genes, pathways, cell types, and evidence. That structure may help readers compare related disruptions, inspect how conclusions were assembled, and identify where an interpretation depends on analogy rather than direct measurement.
For example, an atlas entry can start with a measured response in a particular cell type, bring in published work about a related pathway, and propose a biological explanation. These are three different evidentiary layers: the observed expression change, the literature connection, and the mechanism inferred from both. The latter two may help prioritize a question, but they are not equivalent to experimentally demonstrated causation.
The public framework repository includes runtime code, corpus tooling, notebooks, and material for the manuscript’s analyses. Its instructions distinguish reproducing saved manuscript analyses locally from running new model calls. Access to the code and artifacts makes the work easier to inspect, though nobody has independently reproduced every biological interpretation.
Examples show where result ends and hypothesis begins
The authors use Tsc1 and Tsc2 to show how a broad screen can reveal a cell-specific difference. The genes have related roles in regulating mTOR, a pathway involved in cell growth and metabolism. In the paper’s example, Tsc1 and Tsc2 perturbations showed correlated effects in several neuronal populations, but the cerebellar GABAergic-neuron results diverged: Tsc2 disruption produced 83 significant differentially expressed genes, while Tsc1 had little effect in those cells.
The paper labels this a potential knowledge gap and does not claim a resolved mechanism. The contrast may give researchers a precise cell population and set of changes to investigate, but the expression data do not explain why the difference occurred or what it means for disease. A literature-based expectation can also mislead. The paper discusses cases where assumptions from one cellular context did not hold in another.
OpenAI highlights a second example involving DCTN1, a gene associated with Perry syndrome, a neurodegenerative disease with Parkinson-like symptoms. In the mouse atlas, Dctn1 disruption increased expression of cholesterol-production genes. The agents connected the observation to literature about cholesterol transport and suggested testing whether cholesterol distribution changes in neurons after DCTN1 disruption.
That proposal is a testable lead. It is no evidence yet that altered cholesterol distribution causes neurodegeneration or that correcting it would protect neurons. The announcement describes questions for laboratory follow-up and reports no experiments confirming the proposed chain.
What the 32-minute figure measures
According to the authors, the 32-minute result refers to parallel analysis of the existing data. It does not include generating the mouse-brain atlas, and it is not the time required to discover or validate a biological mechanism. Parallel agents can work on separate perturbations at once, which shortens the computational analysis stage.
The paper compares this runtime with an illustrative estimate of months to a year for serial human analysis and literature review. Its figure caption says the estimate assumes an hourly wage of $22, 15 minutes to interpret each perturbation, and 10 minutes per paper read. The authors describe this as an estimate and not as measured human performance. Actual work depends on how researchers define the task and what they include.
The authors also compared one agent handling larger workloads with many agents handling perturbations separately, holding the model, prompt, tools, and data access fixed. At a workload of 893 perturbations, the single agent cited 11 references, while distributed agents retained 711 times more. That result supports a specific efficiency claim about literature coverage under this setup. More references do not automatically mean more accurate biology, so coverage and correctness should be assessed separately.
Benchmarks provide useful but bounded evidence
The preprint compared agent reports with findings from the atlas study. Across 71 source-study findings, the paper classifies 35 as matched, 13 as refined, nine as partially recovered, and 14 as not covered. For the 55 findings directly testable from differential-expression data, 48 were matched or refined and four were partially recovered. The authors note that conclusions requiring external data were not recoverable from the supplied expression profiles alone.
A second test asked agents to predict the number of expression changes for held-out perturbations in thalamic glutamatergic neurons. The preprint reports a balanced accuracy of 0.705. The task was limited to a specified cell type and prediction target, so it says little about performance across the brain, disease mechanisms, or treatment outcomes.
The paper also tested whether agents could rank perturbations by neuronal depletion using transcriptional evidence. Distributed agents had median recall at rank 50 of 0.36, compared with 0.18 for a single agent and 0.14 for ranking by differential-expression magnitude. This result measures prioritization against observed depletion. It does not confirm a newly proposed mechanism experimentally.
The authors also report misses. The model predicted no response for one held-out target with 1,327 observed differentially expressed genes, while some predicted responses were not seen in the recovered cells. Because of these misses and overcalls, a benchmark score should be read within its setup and not as a general measure of biological reliability.
Expert review measures preference
OpenAI says blinded experts preferred distributed-agent reports over single-agent reports 75% of the time. The preprint describes doctoral-level biological experts assessing reports for confidence, novelty, evidence, and follow-up priority, as well as a matched comparison between distributed and single-agent reports. That evaluation offers a human comparison of generated interpretations, but it does not test whether a proposed mechanism is biologically true.
The article is a bioRxiv preprint posted October 16, 2026, and the repository identifies it as not certified by peer review. The expert evaluations are evidence reported by the study authors and do not represent an independent consensus on the leads. The paper’s author affiliations and competing-interest statement also identify employees of OpenAI and PerturbAI among its authors, including PerturbAI co-founders. That context belongs beside the results, without implying misconduct.
The validation gap remains
Literature support can make an interpretation plausible without directly demonstrating it. The preprint’s own labels distinguish findings that agree with prior reports, those that infer a mechanism, those that disagree with an expectation, and those for which no precedent was retrieved. “No literature” describes a retrieval outcome and does not show that no relevant research exists.
The mouse dataset also sets a boundary on claims about people. A perturbation in mouse brain cells can suggest a translational research question, but it is not a result in patients. Neither the OpenAI announcement nor the materials reviewed here report completed experiments validating the highlighted DCTN1/cholesterol mechanism or establishing a treatment benefit.
The authors call for evaluation on independent datasets and prospective experiments to establish how well the approach generalizes. Reproducing saved analyses checks parts of the computational workflow. A deeper test would be a separate group tracing a claim back to cell-level evidence and then testing it experimentally.
The next test is a specific claim
The clearest practical use of the atlas is to choose a claim narrow enough to inspect. A researcher can check the reported gene and cell type, review the underlying expression evidence, read the cited papers, and decide whether the proposed mechanism warrants an independent experiment. That sequence turns an agent-generated lead into a tractable research question and leaves the model’s narrative as a starting point.
Distributed agents appear to have broadened and accelerated evidence-linked interpretation of an existing screen, with benchmark results that support several defined tasks. The harder test is whether those advantages hold on independent datasets and whether prioritized hypotheses survive prospective experiments. Until then, distributed biological reasoning is best understood as a way to surface and organize research leads. It has not produced confirmed disease mechanisms or treatments.